The Canvas Notebook
The canvas notebook shows the open flow as Python code, one cell per statement, in the Notebook mode of the Code panel. It uses the editor of a catalog notebook, with the same cells, shortcuts, undo, drag and completions. By default it has no kernel: running a cell writes your edits onto the canvas and runs the cell's node where the flow runs. In the desktop app you can also run it on a kernel, where cells run as real Python. This page covers what the cells contain, what Run does for each kind of cell, what a sync refuses, running on a kernel, and how the notebook behaves in each deployment.
See it: a filter cell pushed to the canvas, and a Sort node added on the canvas back in the notebook
Opening it
Open the Code panel (Ctrl/Cmd+G) and pick Notebook, or click Modify in notebook on a flow's page in the Catalog, which opens the flow with the notebook already showing. The panel stays open while you click the canvas or switch flows; a double-click on an empty spot of the canvas closes it, and closing it keeps your edits. The notebook renders the flow:
- The leading cells hold the imports, the flow parameters and the canvas's visual groups (
cleaning = ff.FlowGroup("Cleaning", color="blue"), a nested group withparent_group=), then one cell per statement in the order the flow runs; a cell holds every node its statement chains together, and a node inside a group ends its call with.add_to_group(cleaning). - Cells use the Python API (
import flowfile as ff): fluentFlowFramecalls for built-in transforms, and the native node classes (ff.Gate,ff.RunFlow,ff.PythonScript, custom nodes, parameters) for the rest. - A Python Script node written in its drawer is a
@ff.python_scriptfunction without areturn: the body is the script as written, its cells separated by# %%markers, and the frames it reads go in the call below it (python_script_2 = _script_2(df)). A script that would not come back from that form unchanged, such as one holding a multi-line string, is anff.PythonScript(cells=[...])call instead. - A Polars Code node holding a function is that function as written, followed by the call that wires it (
transformed_5 = df.polars_code(high_value)); rename the function or its parameters and the node keeps your names. A node holding a snippet is a generated_polars_code_<id>(input_df)function whose body is the snippet with its result returned; edit the body and it stays a snippet, rename the function or a parameter and it becomes a function node. - A node's variable is its node reference when it has one, else a label derived from its type and id (
filtered_12). - Dropping, connecting or saving a node on the canvas updates the cells within a couple of seconds; a cell you edited keeps your text. Moving a node changes nothing.
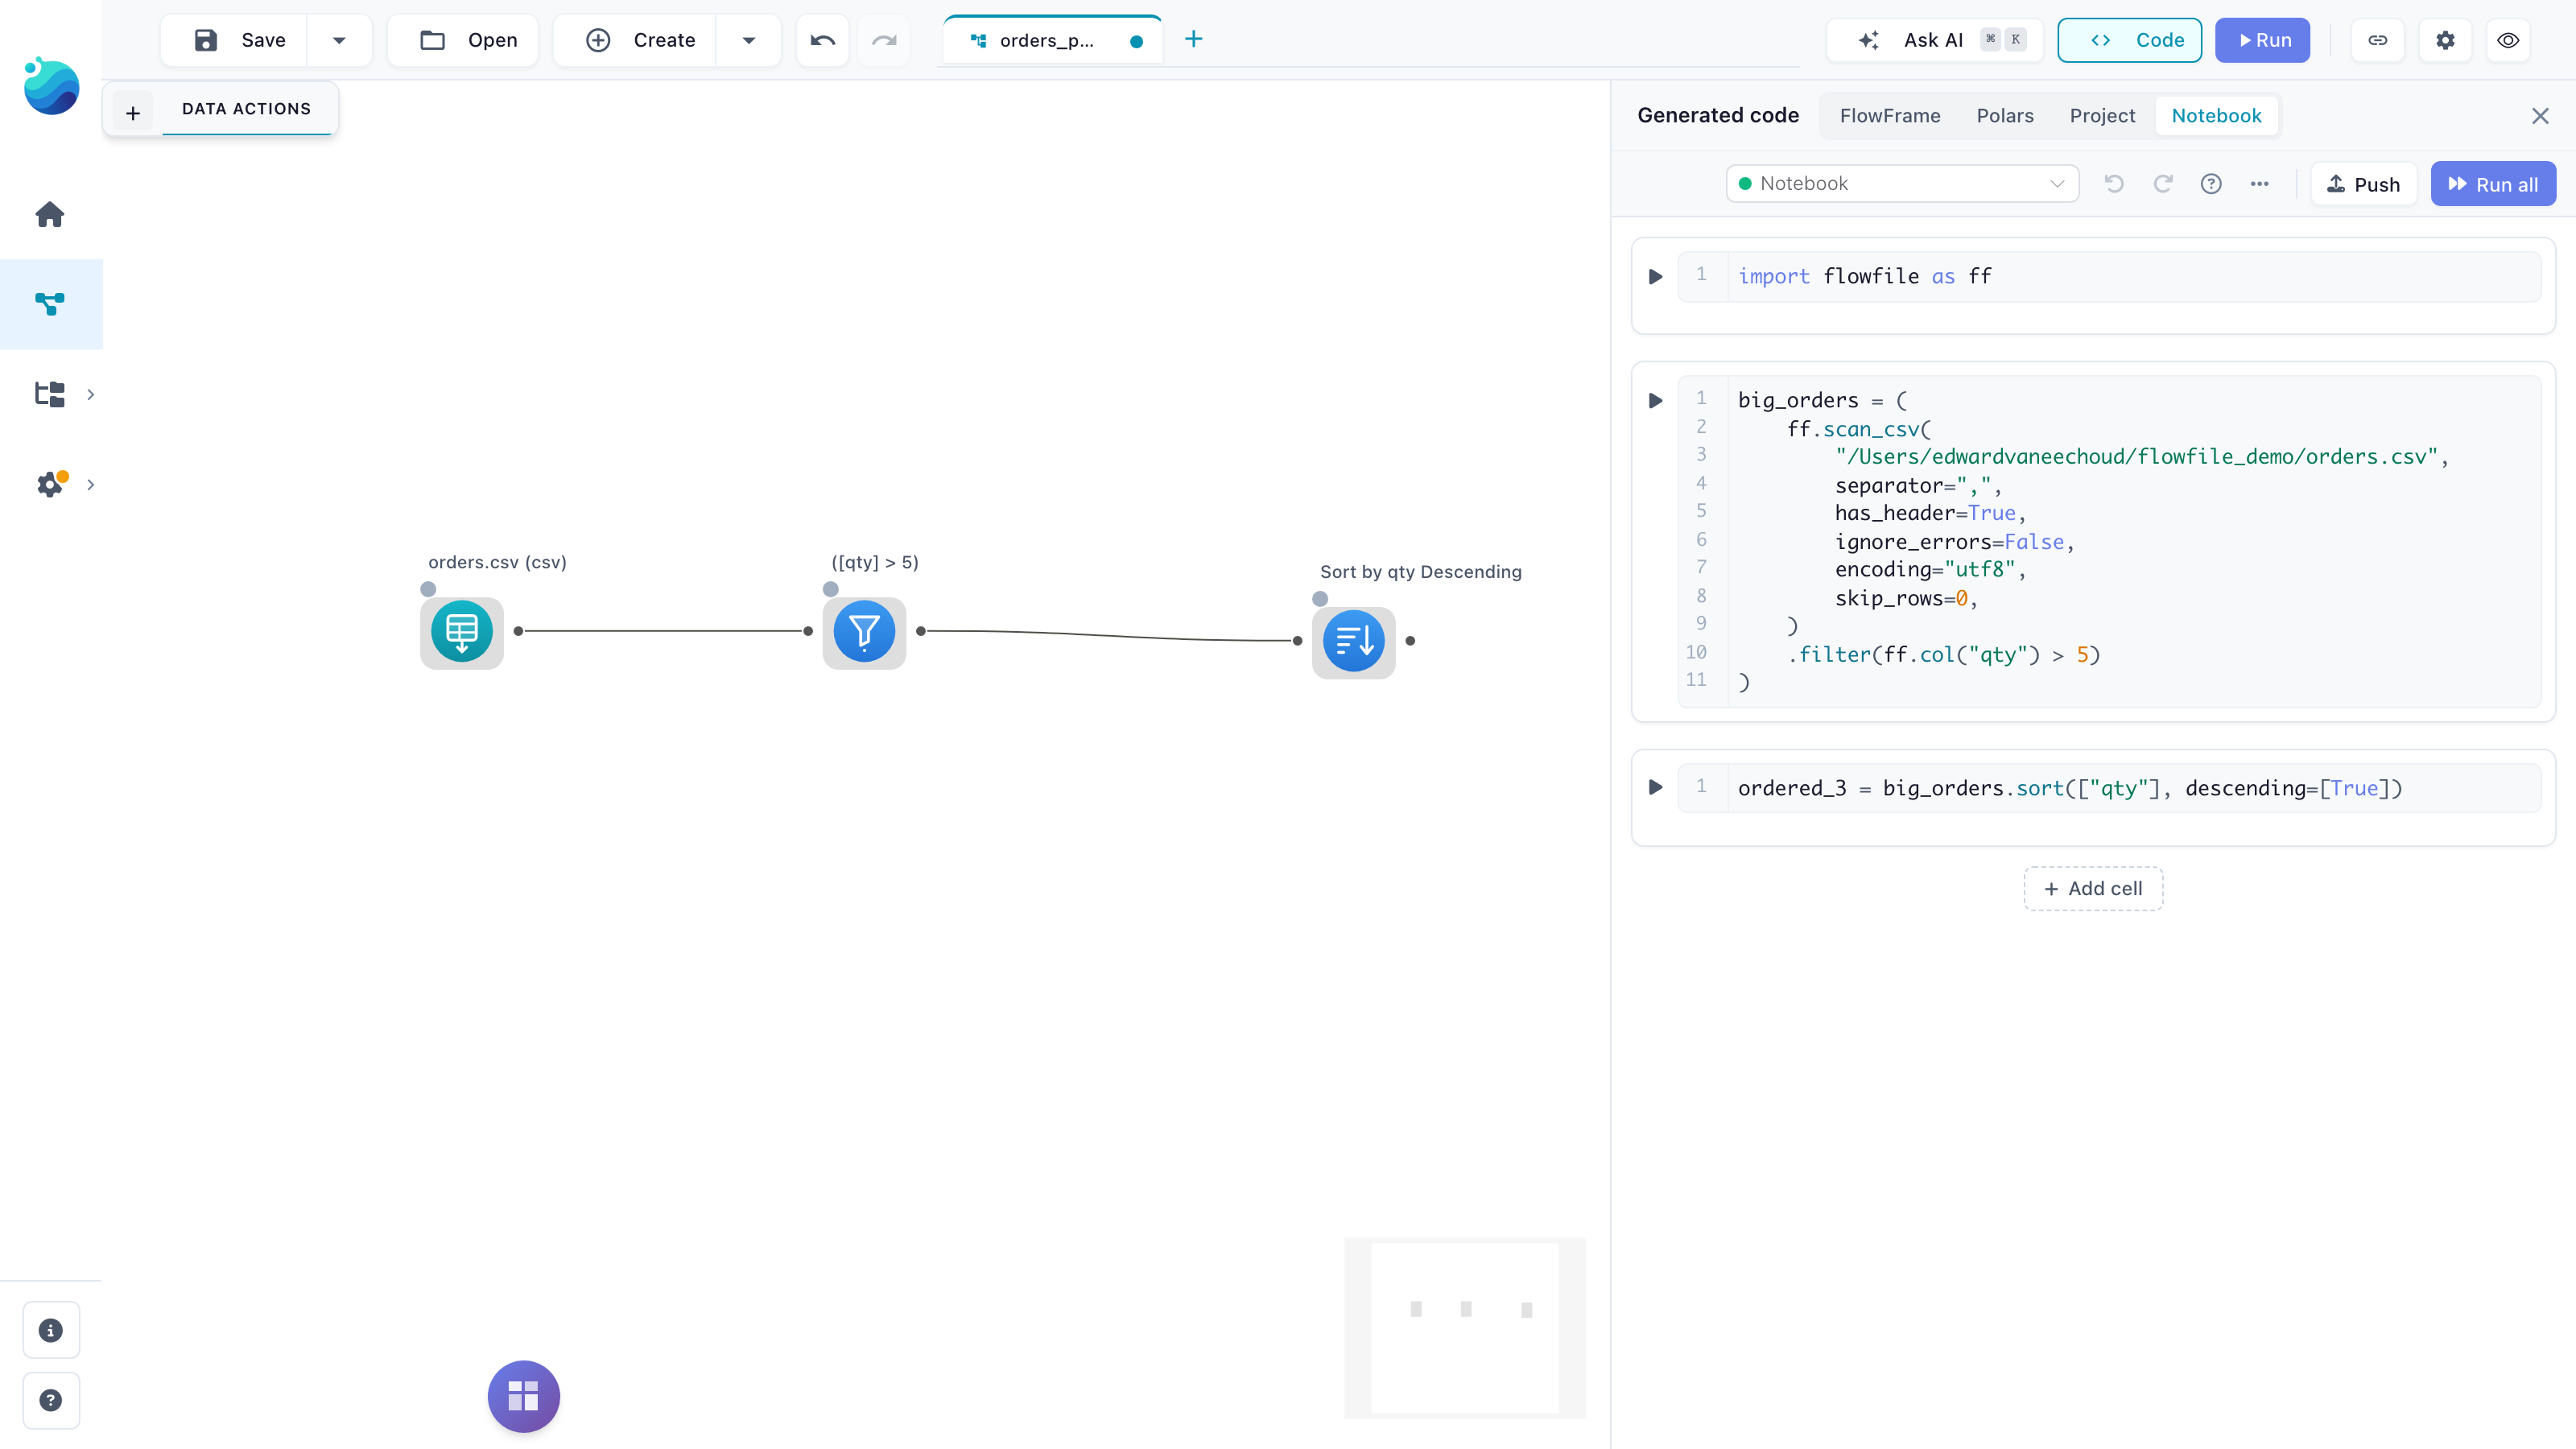
The code is rendered on the server and needs no Python session, no kernel and no Docker, so every user can open it in every deployment.
Placeholder cells
A node the notebook cannot express as code becomes a placeholder cell that still binds the node's output to a variable, so the cells below it keep working:
enriched = ff.canvas_node(7, joined)
ff.canvas_node(node_id, *inputs, output=None) adopts canvas node 7 with its current settings and wires it to the frames passed. The comment on the cell's first line says why it is a placeholder, for example:
| Reason on the cell | Fix |
|---|---|
| not configured yet, inputs not fully connected | Configure or connect the node on the canvas. A placeholder for an unconfigured node can also be replaced with code. |
| downstream of node N, which is not editable as code | Fix node N; everything below it follows. |
| nodes below it read its output, which ff.explore does not return | An Explore data node feeds other nodes, which only code can wire. Connect them to the node's input instead. |
| headers or query parameters hold a credential | A REST API reader with a key in its headers or parameters. Move the key to a secret. |
| No code generator implemented for node type '...' | The node type has no code form; edit it on the canvas. |
A Polars LazyFrame node (a frame passed in from Python) is unsupported: it cannot be rebuilt, and a flow that contains one cannot be synced until the node is replaced on the canvas.
Running a cell
This section describes the notebook with No kernel picked. Cell code never runs as Python on the server. The server reads the cells as a description of the flow, and data is only computed where the flow runs: the backend and worker, and a Python Script node on its kernel.
Run (the cell's run button, Shift+Enter or Cmd/Ctrl+Enter) first syncs the cells to the canvas when the notebook no longer matches the canvas (a cell edited, added, removed or moved), then does what the cell's kind calls for:
| Cell | Example | What Run shows |
|---|---|---|
| Imports | import flowfile as ff |
Nothing. |
| Groups | cleaning = ff.FlowGroup("Cleaning", color="blue") |
Nothing. |
| Parameters | min_quantity = ff.add_flow_parameter(flow, ff.Parameter("min_quantity", default=8, type="integer")) |
The flow's parameters, each with its name, type and default, read from the canvas after the sync. |
| Node | filtered_2 = source_1.filter(ff.col("quantity") >= min_quantity) |
Runs the cell's last node and everything it depends on, honouring gates, then shows up to 100 of its rows. A writer cell writes, and a change-tracking cursor or Kafka offsets then move with what it wrote. Any other node cell only shows rows and leaves them where they are. |
| Plain value | threshold = 8 |
Nothing. |
A node cell's table is the node's preview, the one the canvas shows, so it holds at most 100 rows and its title says so. A longer result ends with "showing 100 of N rows" when its row count is known; when it is not, as for a lazy result the run never counted, the title says the total is unknown. In the Performance execution mode, where a run keeps no rows per node, the cell then fetches its node's rows the way the preview's Fetch Data button does, so Run can take a moment longer. A node with more than one output, such as a gate with an else output, shows its first output, and a writer shows the rows it received. A node that failed, or did not run because a node above it failed, shows Node #N failed: and that error instead of rows; after a cancelled run the cell says the node did not run. When the cell's node is no longer on the canvas, because a sync or a canvas edit removed it, the cell says Node #N is not on the canvas. and reads nothing.
Run and preview on canvas in a node cell's ⋯ menu runs the cell the same way, then opens the node's preview on the canvas.
A cell cannot print, display or compute rows: a node cell's output is always its node's preview. Code outside the flow description, such as print(...), a loop, import os or a lambda, stops the sync and nothing reaches the canvas: the failing line is highlighted and the cell's output gives the reason, for example Line 1: `import os` is not part of the notebook's flow code; this needs a kernel.
Edited, synced and failed cells
Each cell carries a marker that compares it with the canvas:
| Marker | Meaning |
|---|---|
| Edited | The cell's code differs from what the canvas holds; the next Run, Run all or Push syncs it. |
| Synced | The canvas holds the cell's code. |
| Sync failed | The last sync stopped at this cell, and its output says why. Editing the cell marks it edited again. |
These markers take the place of the catalog notebook's Code changed — rerun and Earlier cells changed — rerun labels: the canvas notebook keeps no variables between runs.
Run all and Push
Run all syncs when the notebook no longer matches the canvas (a cell edited, added, removed or moved), runs the whole flow as Run in the top toolbar does, then fills in every parameters and node cell's output; imports and plain cells show nothing.
Push only syncs: it writes the cells onto the canvas and runs nothing.
See it: a longer example with a group-by, filter and join pushed from one cell
What a sync does
Run, Run all and Push sync the same way. The server reads every cell top to bottom on a fresh copy of the flow, so a name a cell defines is available to the cells below it; no variable is kept from one sync to the next. A cell may only describe the flow, with the calls the notebook itself renders (ff readers, transforms and writers, the native node classes, parameters and plain values) and a few Polars frame methods it renders another way, such as .limit(n), .tail(n) and .write_ipc(path). Such a method places the node the Python API builds for it, most often a Polars Code node, and the next render shows that node instead of your call. ff.LazyFrame(data) and ff.DataFrame(data) work the same way: they take Polars' constructor arguments (schema=, orient= and the like) and place a Manual Input node holding the data, which the next render writes as ff.from_raw_data(...). The result is applied to the canvas as one step that Undo reverts.
A sync runs no node and opens no connection. A source, or a node whose columns depend on its data (Polars code, pivot, custom nodes, a data cleansing that removes null columns), keeps the columns the canvas shows while its settings are unchanged; a new or edited one takes the columns its cell declares, the columns Polars works out from the call when .tail(n) or a similar Polars frame method, or with_columns, select, filter or sort, places a Polars Code node, the header of the local file it reads or a catalog table's registered columns, and otherwise the sync treats it as having no columns.
A sync keeps the id, position, description and cached results of every node the edit does not touch, and a lowercase variable name assigned in a cell becomes that node's reference. Visual groups follow the cells too: a node whose cell changed lands in the group its .add_to_group(...) names (a new ff.FlowGroup in the groups cell becomes a new box, a renamed or recoloured one updates the box), a node whose cell did not change keeps its canvas group, and a box left empty is removed.
What a sync refuses or asks about
A sync is refused, with the reason on the failing cell or in a message, when:
- the canvas changed since the cells were rendered: the panel refreshes the cells, keeps your edits and says the canvas changed; run or push again;
- a cell holds code outside the flow description (it needs a kernel); the cell shows the line;
- the flow contains a Polars LazyFrame node (a cell cannot create one:
ff.FlowFrame(pl.LazyFrame(...))needs a kernel); - a cell places a custom node that is not installed, or whose installed file fails to load;
- a REST API reader carries an inline secret instead of a secret name;
- a source or writer names a connection you cannot use, or, in a Docker deployment, a cloud reader or writer has a local path or no connection;
- a cell calls a build-time write or runs a flow; notebook mode lists the calls.
Push asks for confirmation first, listing the reasons, when the sync deletes nodes, changes a node's type, changes flow parameters (parameter changes are not undone by Undo), takes a node reference from another node, drops an input a cell did not rebuild, changes the names a Python Script node reads its inputs by, names a kernel you do not own, or places a node it could not check because a node above it has no known columns (the run checks it). Run and Run all ask only when the sync deletes nodes, and show the other reasons as a warning once the sync is applied.
Running on a kernel
In the desktop app, and with pip install flowfile in the default mode, the notebook toolbar has a kernel picker. Pick a notebook kernel, a kernel on the Notebook image (the Lite image with this app's flowfile installed, published for every Flowfile version), and the cells run as real Python in a session on that kernel: loops, print, other imports and display(...) work, as in a script. When you have no such kernel, Create notebook kernel in the toolbar sets one up in one click: created, started and selected for this flow; nothing is installed on your machine. When the Notebook image is not here yet, the button reads Download image and create notebook kernel and downloads it first (several hundred MB, once per Flowfile version). Customise… in the picker opens the kernel form with the same settings filled in. A flow you never picked a kernel for selects a notebook kernel by itself as soon as one exists (a running one first). Pick No kernel to run on the canvas instead; that choice is remembered for the flow.
| Action | With a kernel picked |
|---|---|
| Run | Runs the cell as Python in the session. The canvas does not change. |
| Run all | Runs every cell in the session. |
| Push | Runs every cell again in a fresh session on the kernel, then applies what they build to the canvas as one step, with the same review as without a kernel. The session is then reseeded from the canvas. |
| Run and preview on canvas (⋯) | Pushes first when the notebook differs from the canvas, then runs the node on the canvas, as without a kernel. |
| Reset session (⋯) | Drops the session's variables and binds one variable per canvas node again. |
| Stop | Shown beside a running cell's run button. Interrupts the cell, and cancels the canvas run it is waiting on for rows. |
When the session opens, every canvas node is bound to its variable, so a cell can use filtered_2 without running anything first. display(frame) shows rows. The kernel computes them itself for frames built on rows it has (manual input, and transforms over rows it was handed); for any other node that is on the canvas, such as a file or catalog table reader, a database reader or a Python Script node, the canvas runs the node and hands its rows to the kernel. A node that exists only in your cells and that the kernel does not run (a file or catalog table read, a database, API or Kafka source, a subflow, a gate, a Python Script on another kernel) is run by the app from the cell's settings, over the rows of its inputs, and its columns are known as soon as the cell builds it; the canvas does not change. So every file a cell names is read by the app, never by the kernel: from the canvas node with the same settings, else from the cell's settings. Only a writer in a cell needs a push: a cell never writes. Running a cell again unchanged does not make its node new: a node a cell builds with a canvas node's settings and inputs keeps reading that canvas node's rows, so a Python Script cell can be run again, alone or with Run all, and its frame still shows rows. After an edit to the cell, or to a cell above it, the app runs the node again from the cell.
A canvas node whose columns are only known once it runs, such as a Python Script node without declared outputs, has no columns in the session until the canvas has run it. Once it has, through Run and preview on canvas or a run on the canvas, the next cell you run sees its columns, and so do frames built on it in earlier cells. Showing a node's rows in a session does not move a change-tracking cursor or commit Kafka offsets, unless that node is a writer the canvas has to run.
flowfile_ctx is available in cells, as in a Python Script node (The flowfile_ctx API). An artifact published with flowfile_ctx.publish_artifact in a cell stays in the session: later cells can read it, Python Script nodes on the canvas cannot. To hand a model to the canvas, publish it from the Python Script node's own code, or use flowfile_ctx.publish_global, which stores it in the catalog.
The kernel is busy with the cell while the canvas runs, so that run cannot use the notebook's own kernel. When it would have to run a node on it, such as a Python Script node on that kernel (also inside a subflow or a virtual table's producer), the cell stops at once with a message naming the node. Use Run and preview on canvas for the node first, so the canvas runs it while the kernel is free, or run the notebook on another kernel.
The kernel mounts no folder of this machine: files, catalog tables, saved flows and custom nodes reach it through the app, which also copies the code of your installed custom nodes into the kernel, so a cell can place them. What a cell looks up in the catalog, such as a table's record, a flow reference, a connection's name or ff.kernels, is answered by the app, and stored secrets never reach the kernel in any form: a cloud or database source and a custom node with a secret setting are always run by the app, from the canvas or from the cell's settings. The kernel holds no copy of the catalog database: a cell that opens it itself, through flowfile_core's get_db_context(), stops with a message naming the ff functions to use instead.
In cells, write file paths as they are on your machine (C:\Users\me\data\sales.csv on Windows). The kernel never opens them: Flowfile's readers and list_files are run by the app, and a push stores the path as written. Plain Polars, such as pl.read_csv, or open() cannot see a file on this machine from a cell; use ff.read_csv or ff.scan_csv instead. Writing a file directly from a cell, such as df.write_csv(...), is not possible; an ff writer in a cell adds a writer node, which writes when the flow runs.
Limits:
- Only in the desktop app and in a default
pip install flowfile(FLOWFILE_MODEunset orelectron), for a local connection. Docker deployments keep the notebook without a kernel. - The kernel's
flowfilemust have the same version as the app. After an app update the picked kernel still runs the previous Notebook image, so the toolbar shows Update notebook kernel: it stops the kernel and starts it again, which downloads this app's image and drops what the kernel holds in memory.
Kernels, Docker and deployments
With No kernel picked the notebook starts no Python process and needs no kernel and no Docker. A Python Script node in the flow still runs on its kernel: its cell is an ff.PythonScript or @ff.python_script definition, and running that cell runs the node on its kernel, which needs Docker as it does on the canvas. Python that prints, displays or computes needs a kernel: this notebook on a kernel, a Python Script node or a catalog notebook.
Viewing and editing the cells, and running them while the notebook matches the canvas, work for every user, for their own flows, in the desktop app, with pip install flowfile and in a Docker deployment. Syncing works for every user in the default electron mode: the desktop app, and pip install flowfile unless you set FLOWFILE_MODE. With any other FLOWFILE_MODE (docker in a Docker deployment, or package) syncing needs an admin account, because the catalog lookups a cell can reach do not check each user's access. Other users keep editable cells; Run and Run all when the notebook no longer matches the canvas, and Push, leave the edits in the notebook, and a banner says that syncing needs an admin. The notebook has no settings of its own.
Exporting the notebook
The ⋯ menu in the toolbar saves the cells as a file, so the code can leave Flowfile. Export as Python script… writes a .py file in which every cell opens with a # %% marker (# %% [markdown] for a Markdown cell, whose text becomes comments): VS Code, Spyder and Jupytext read the markers as cell boundaries, and a plain python runs the file top to bottom, since the imports cell comes first. Export as Jupyter notebook… writes an .ipynb that Jupyter, VS Code and Colab open, carrying the last output of every cell that ran in the panel. Copy as Python script puts the same script on the clipboard. The desktop app asks where to save; the browser downloads the file. The file is named after the flow, and nothing is sent anywhere: the export is built from the cells as they are in the panel, edits included.
What is not saved with the flow
The notebook is a view of the flow. Edits are kept in this browser window until a sync writes them to the canvas; reloading the page drops them. Saving the flow saves the canvas, not the notebook. A cell you add that places no node, such as threshold = 8, is not part of the flow: after a sync it stays in the panel only until the canvas next changes.
Related
- Export to Python: a standalone script or project from the same flow, which does not round-trip.
- Catalog notebooks: notebooks stored in the catalog that run on a kernel.
- Native node classes: the Python API the cells use, and what notebook mode changes.